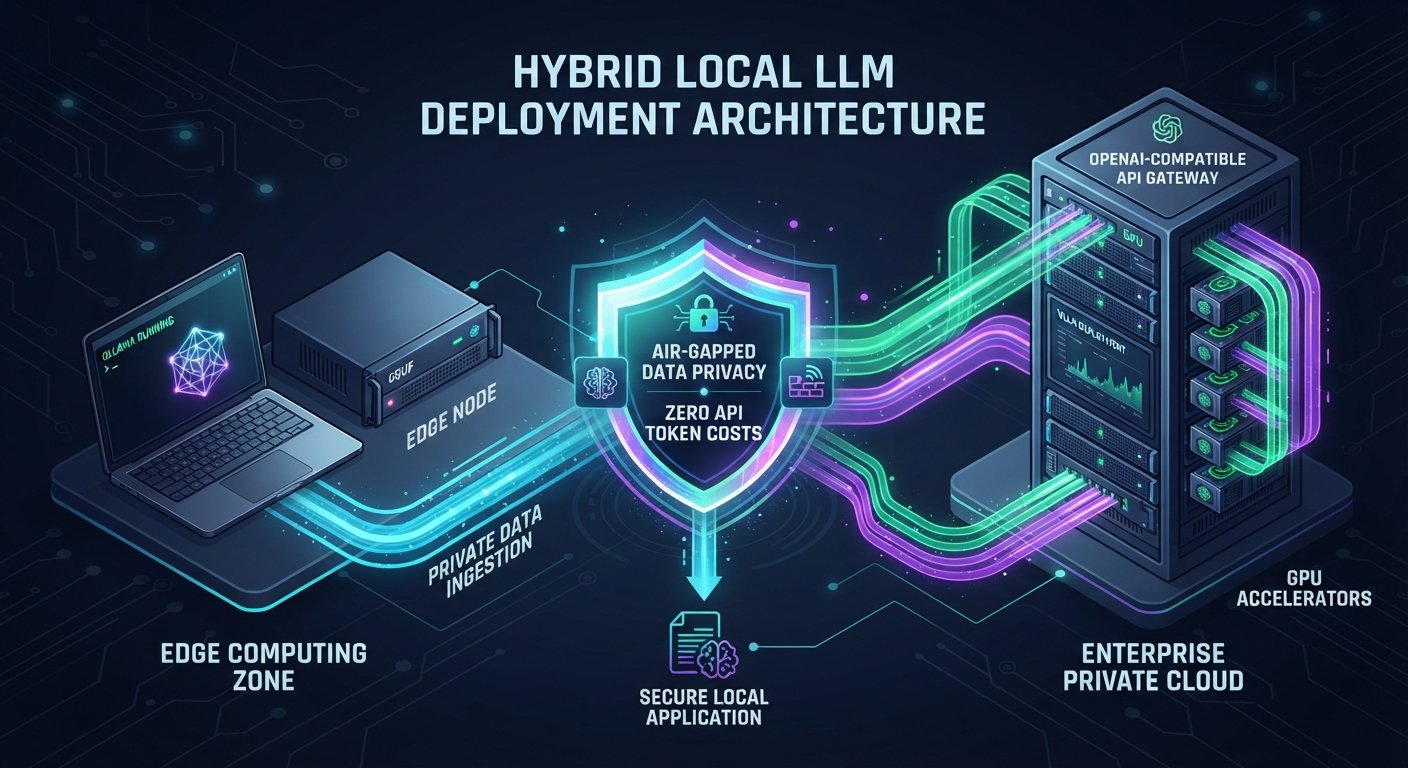
How to Deploy Local LLMs on Edge Devices and Private Servers Using Ollama & vLLM
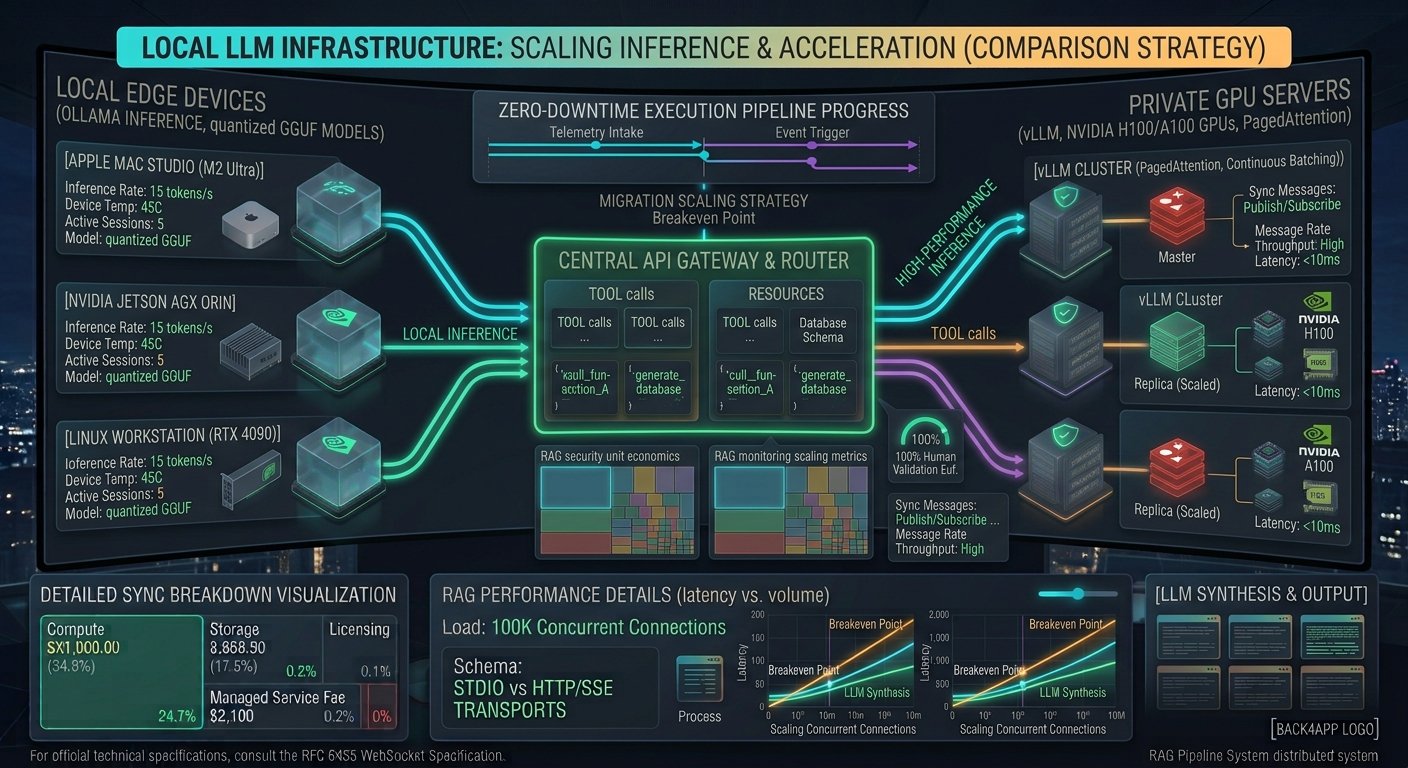
Relying exclusively on commercial cloud LLM APIs presents significant challenges for enterprise software teams:unpredictable token pricing, strict data privacy regulations (GDPR, HIPAA, SOC 2), latency overhead, and network reliance. As open-weight models (such as Llama 3, Mistral, and DeepSeek) approach or surpass proprietary models on specialized tasks, hosting open-weight models internally has become a primary infrastructure objective. Learning how to deploy local LLMs on edge … Read more